Manage Connections
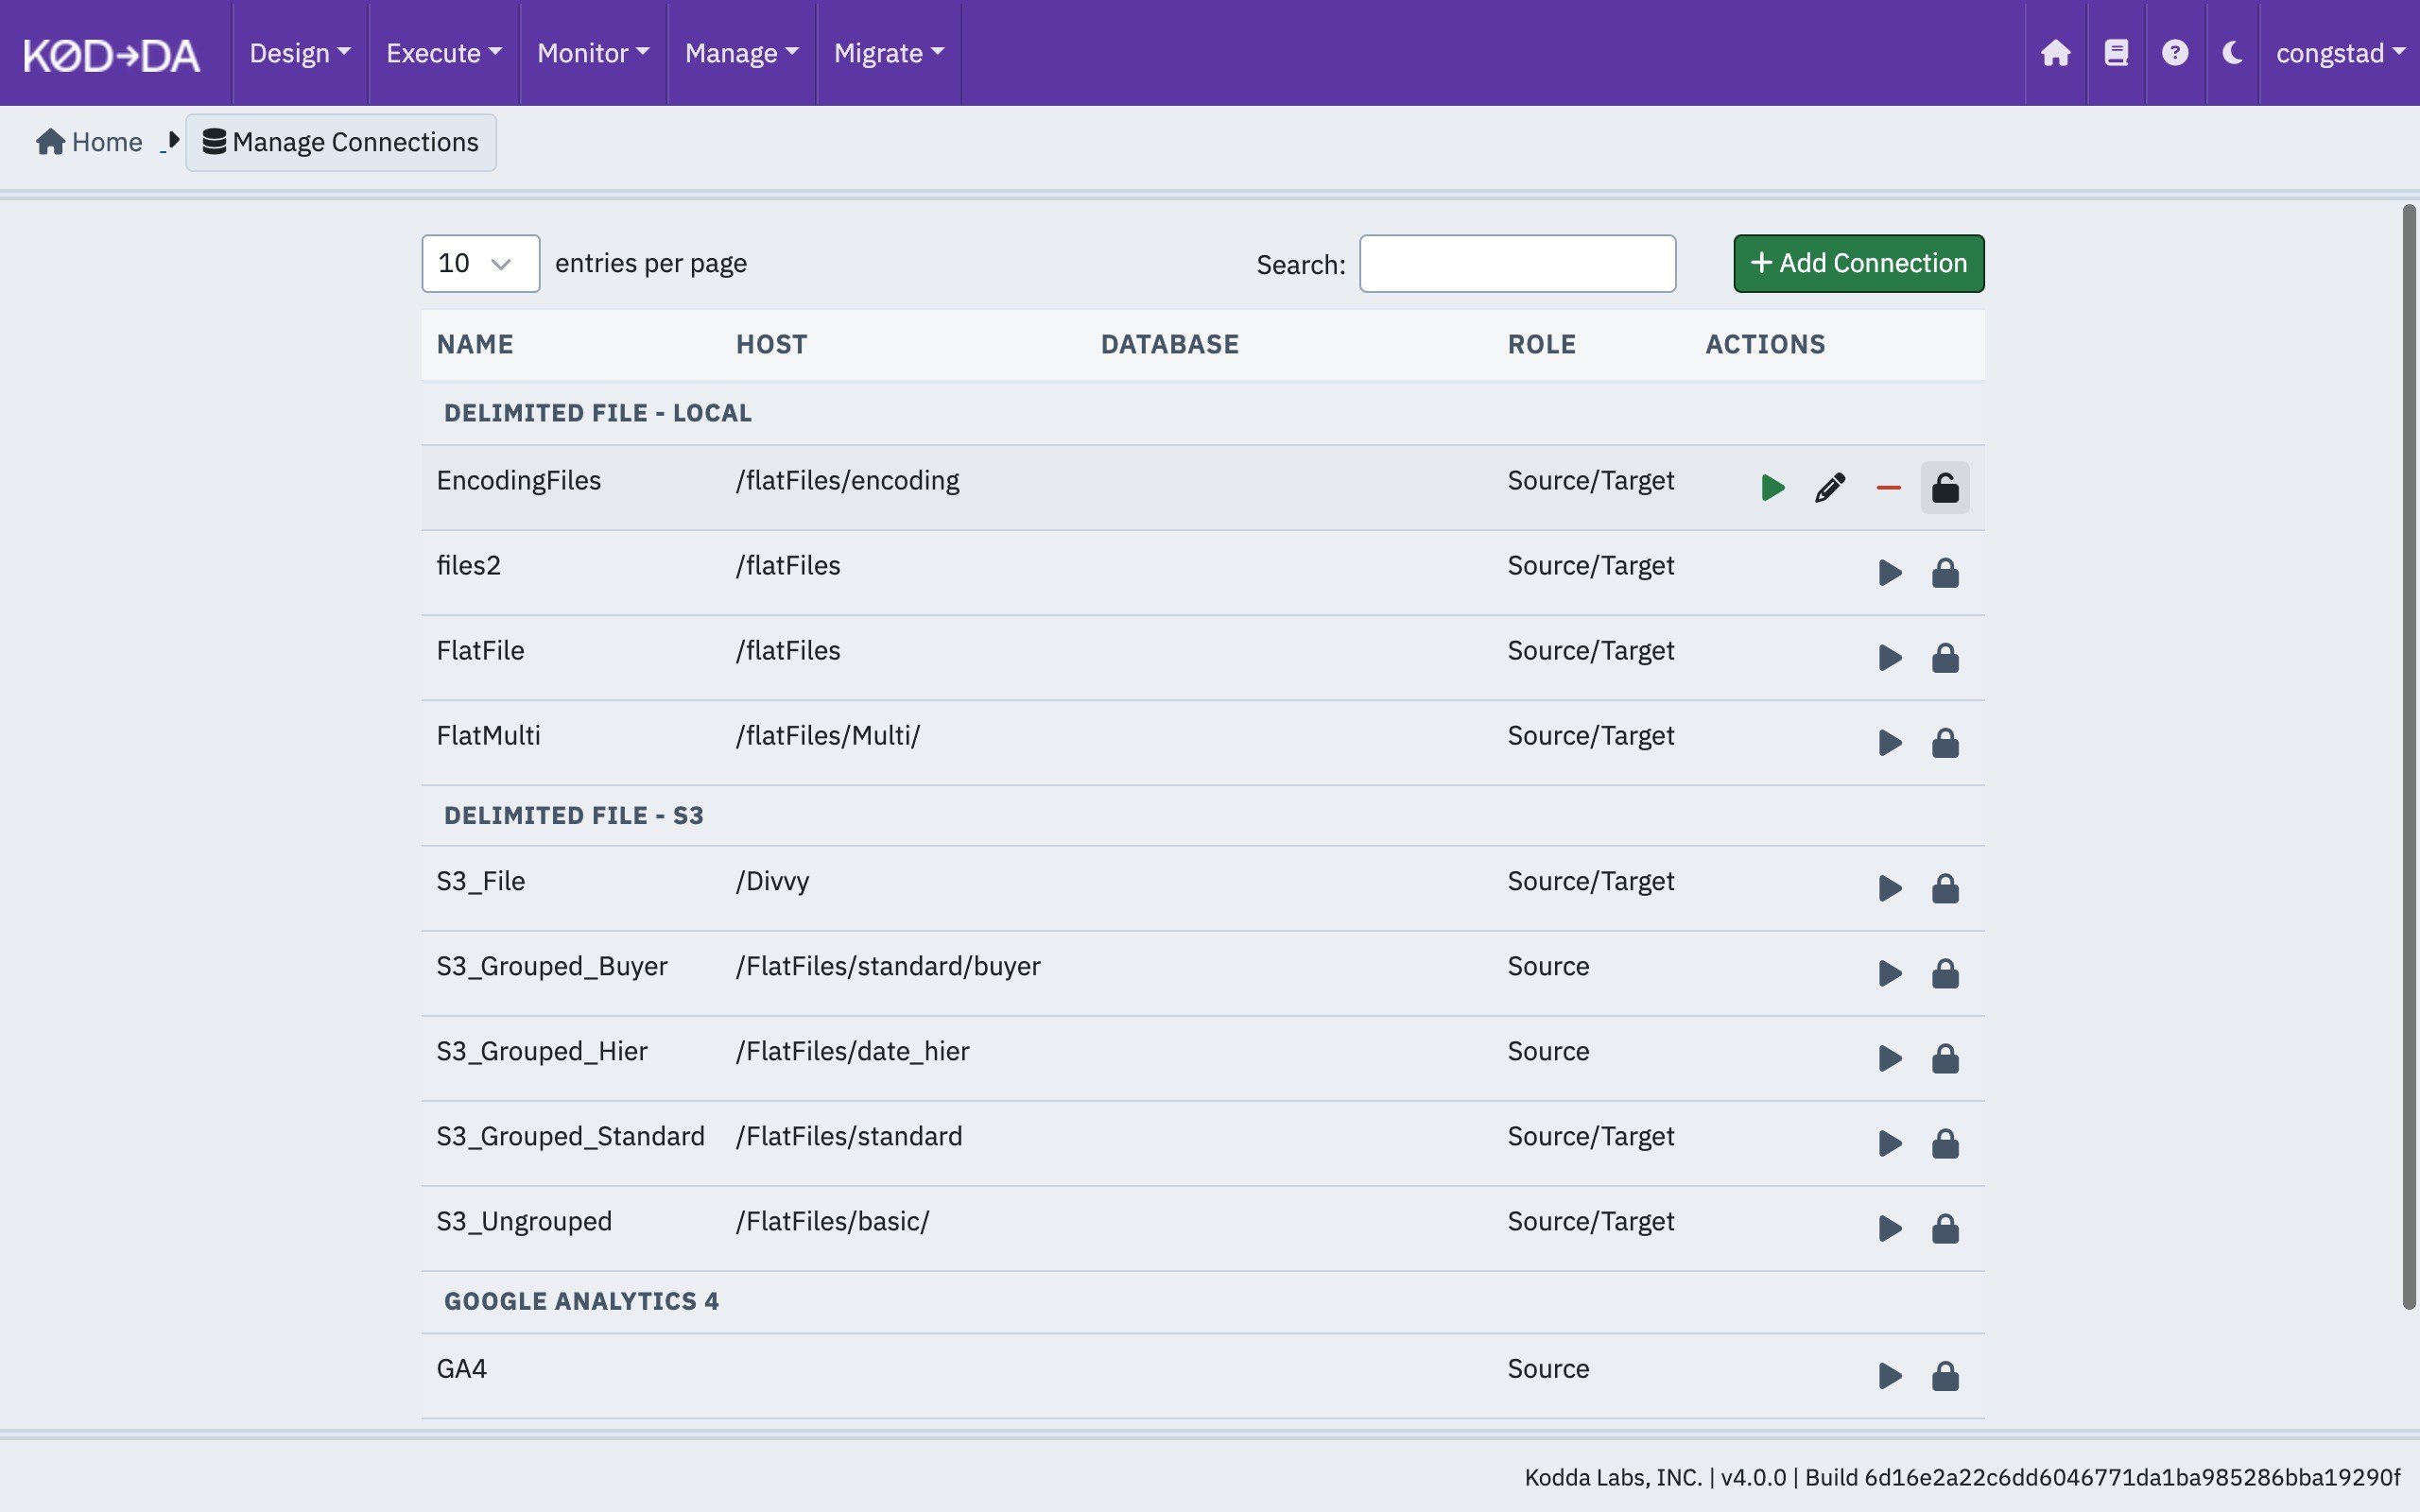
Use the Manage Connections screen to create and modify data source and/or target connections.- To create a new connection, click the + Add Connection button at the top right, choose a Connection Type, and enter the required information.
- Once a connection is created use the

- To edit or delete a connection, click the lock icon on its row to unlock it, then use the pencil (edit) or minus (delete) icon that appears.
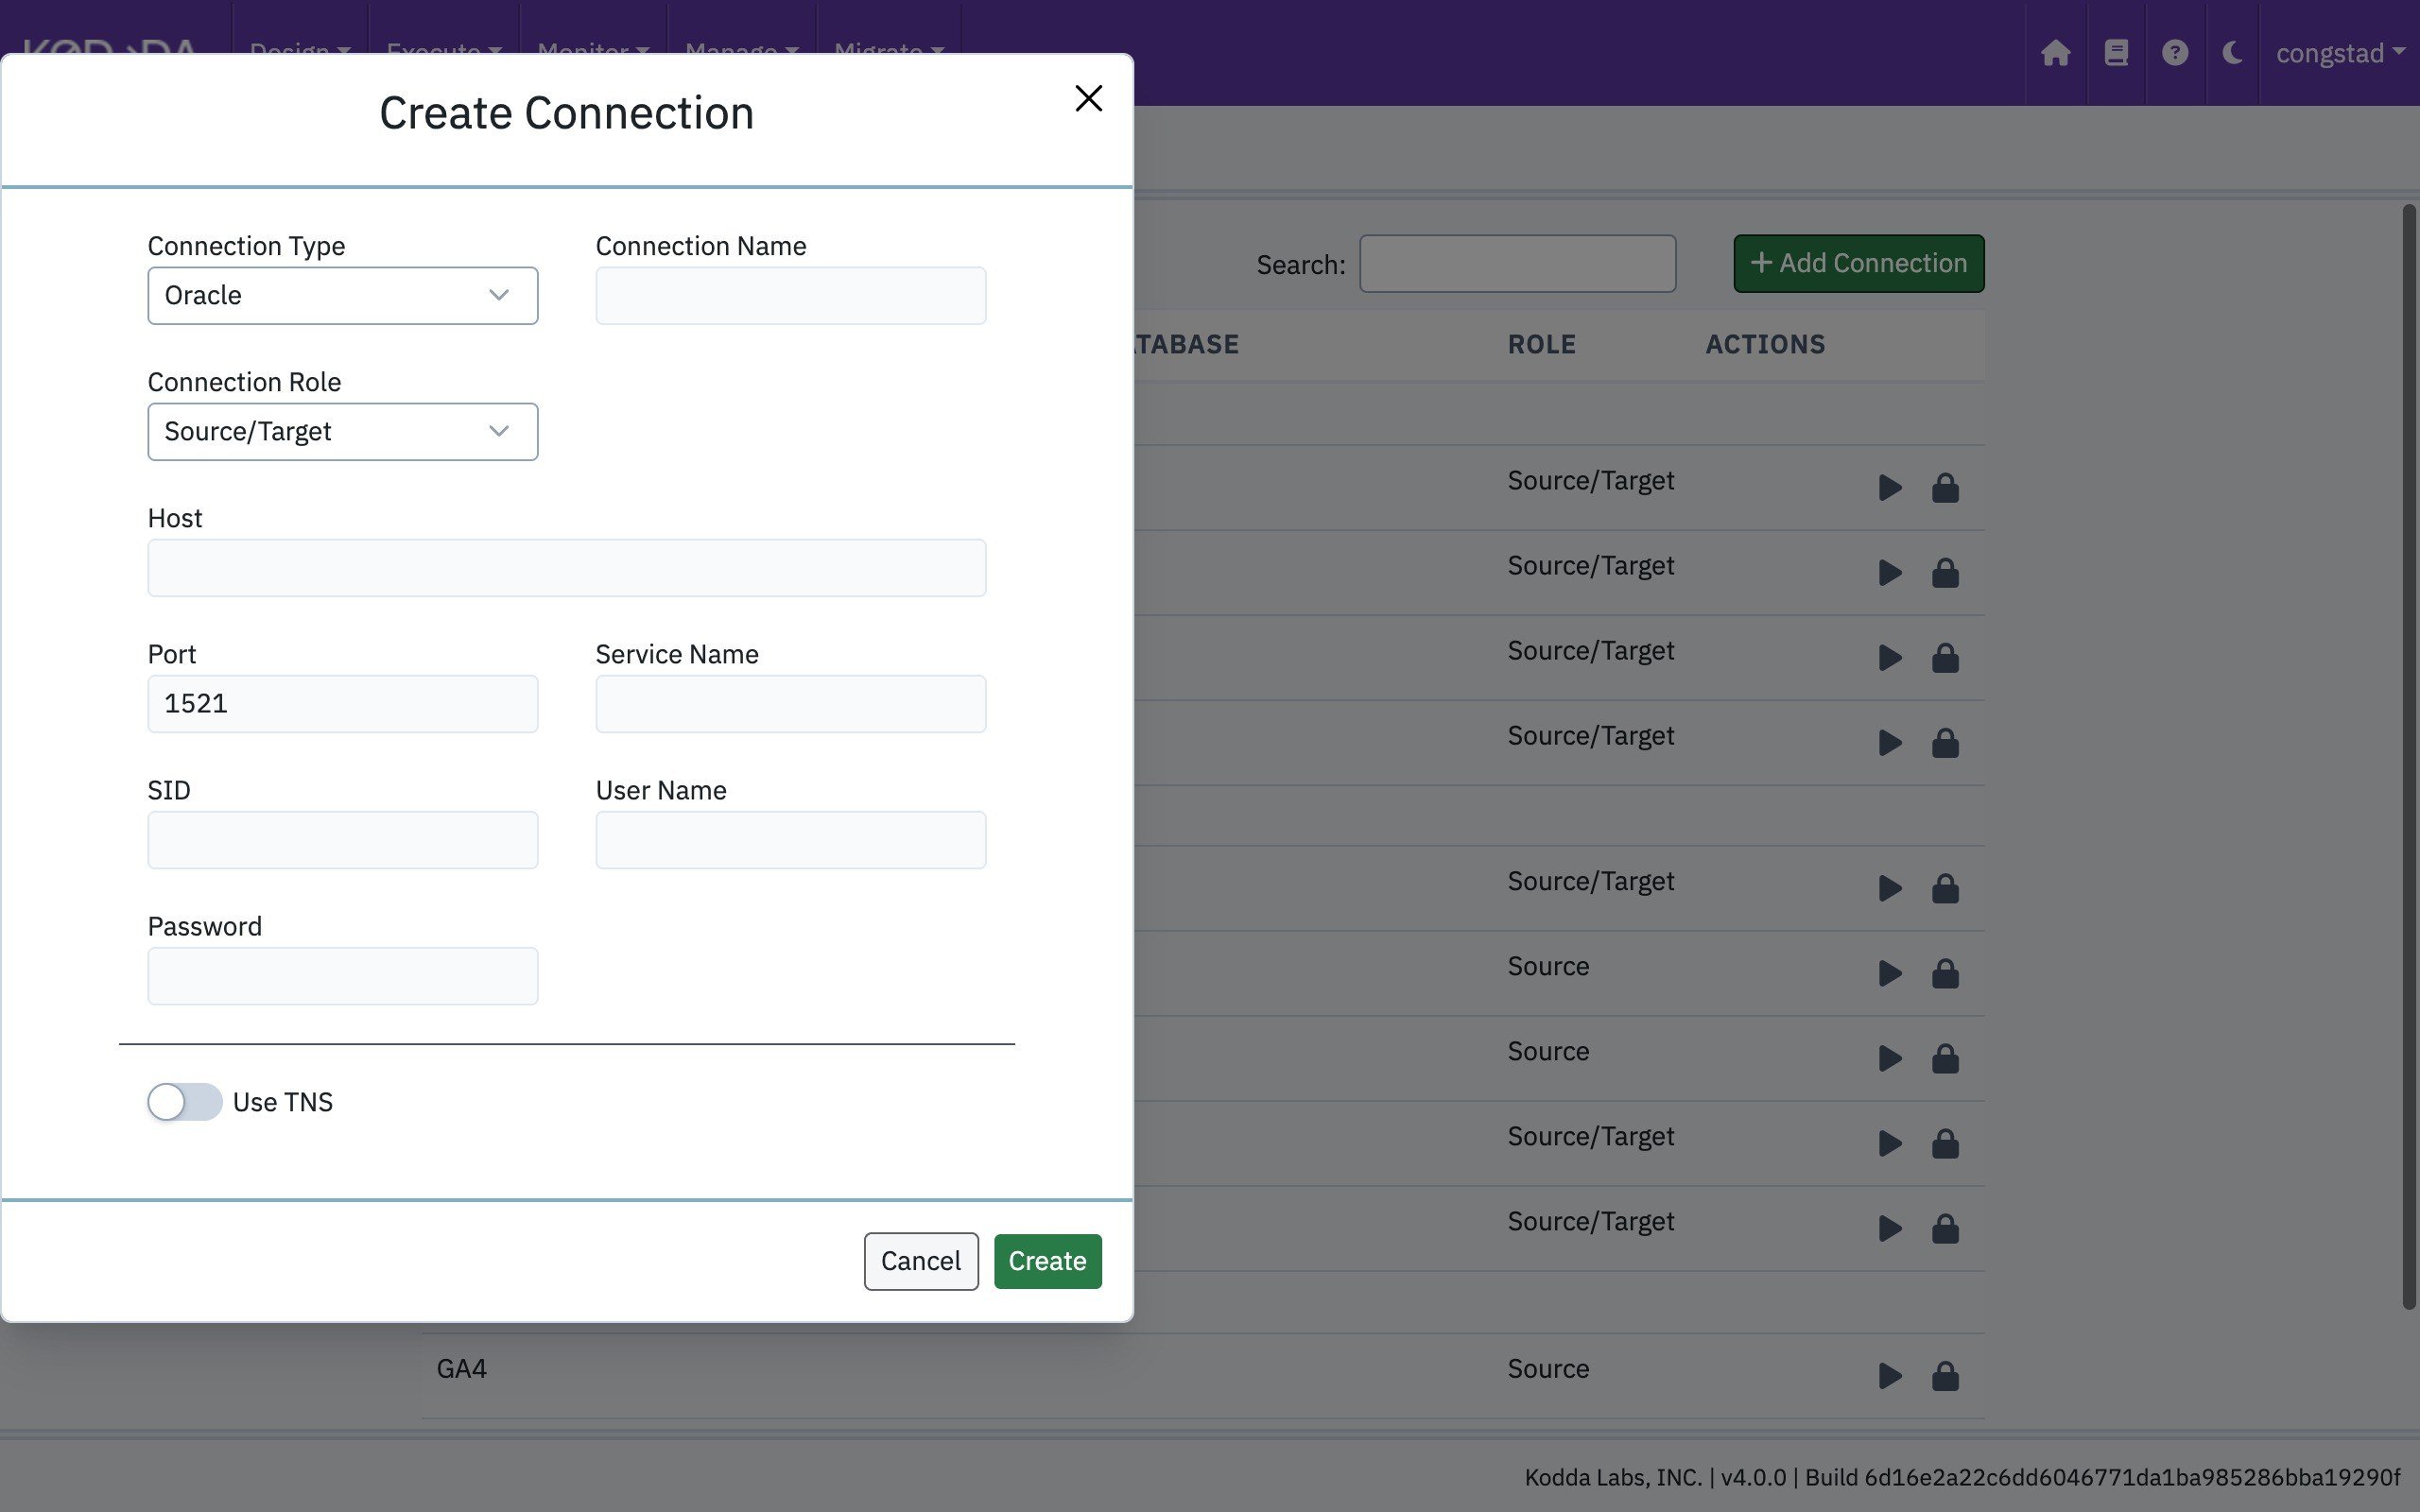
Different connection types have their own unique connection parameters. Consult your database documentation or database administrator for your connection details required.
Example: Oracle
Additional Connection Types
The available connection types are File (delimited or Parquet, on a local file system or S3), Google Analytics 4, Informix, Mail Chimp, MySQL, Oracle, PostgreSQL, Redshift, Salesforce, Snowflake and SQL Server. See the following tables for more detail on each type’s parameters.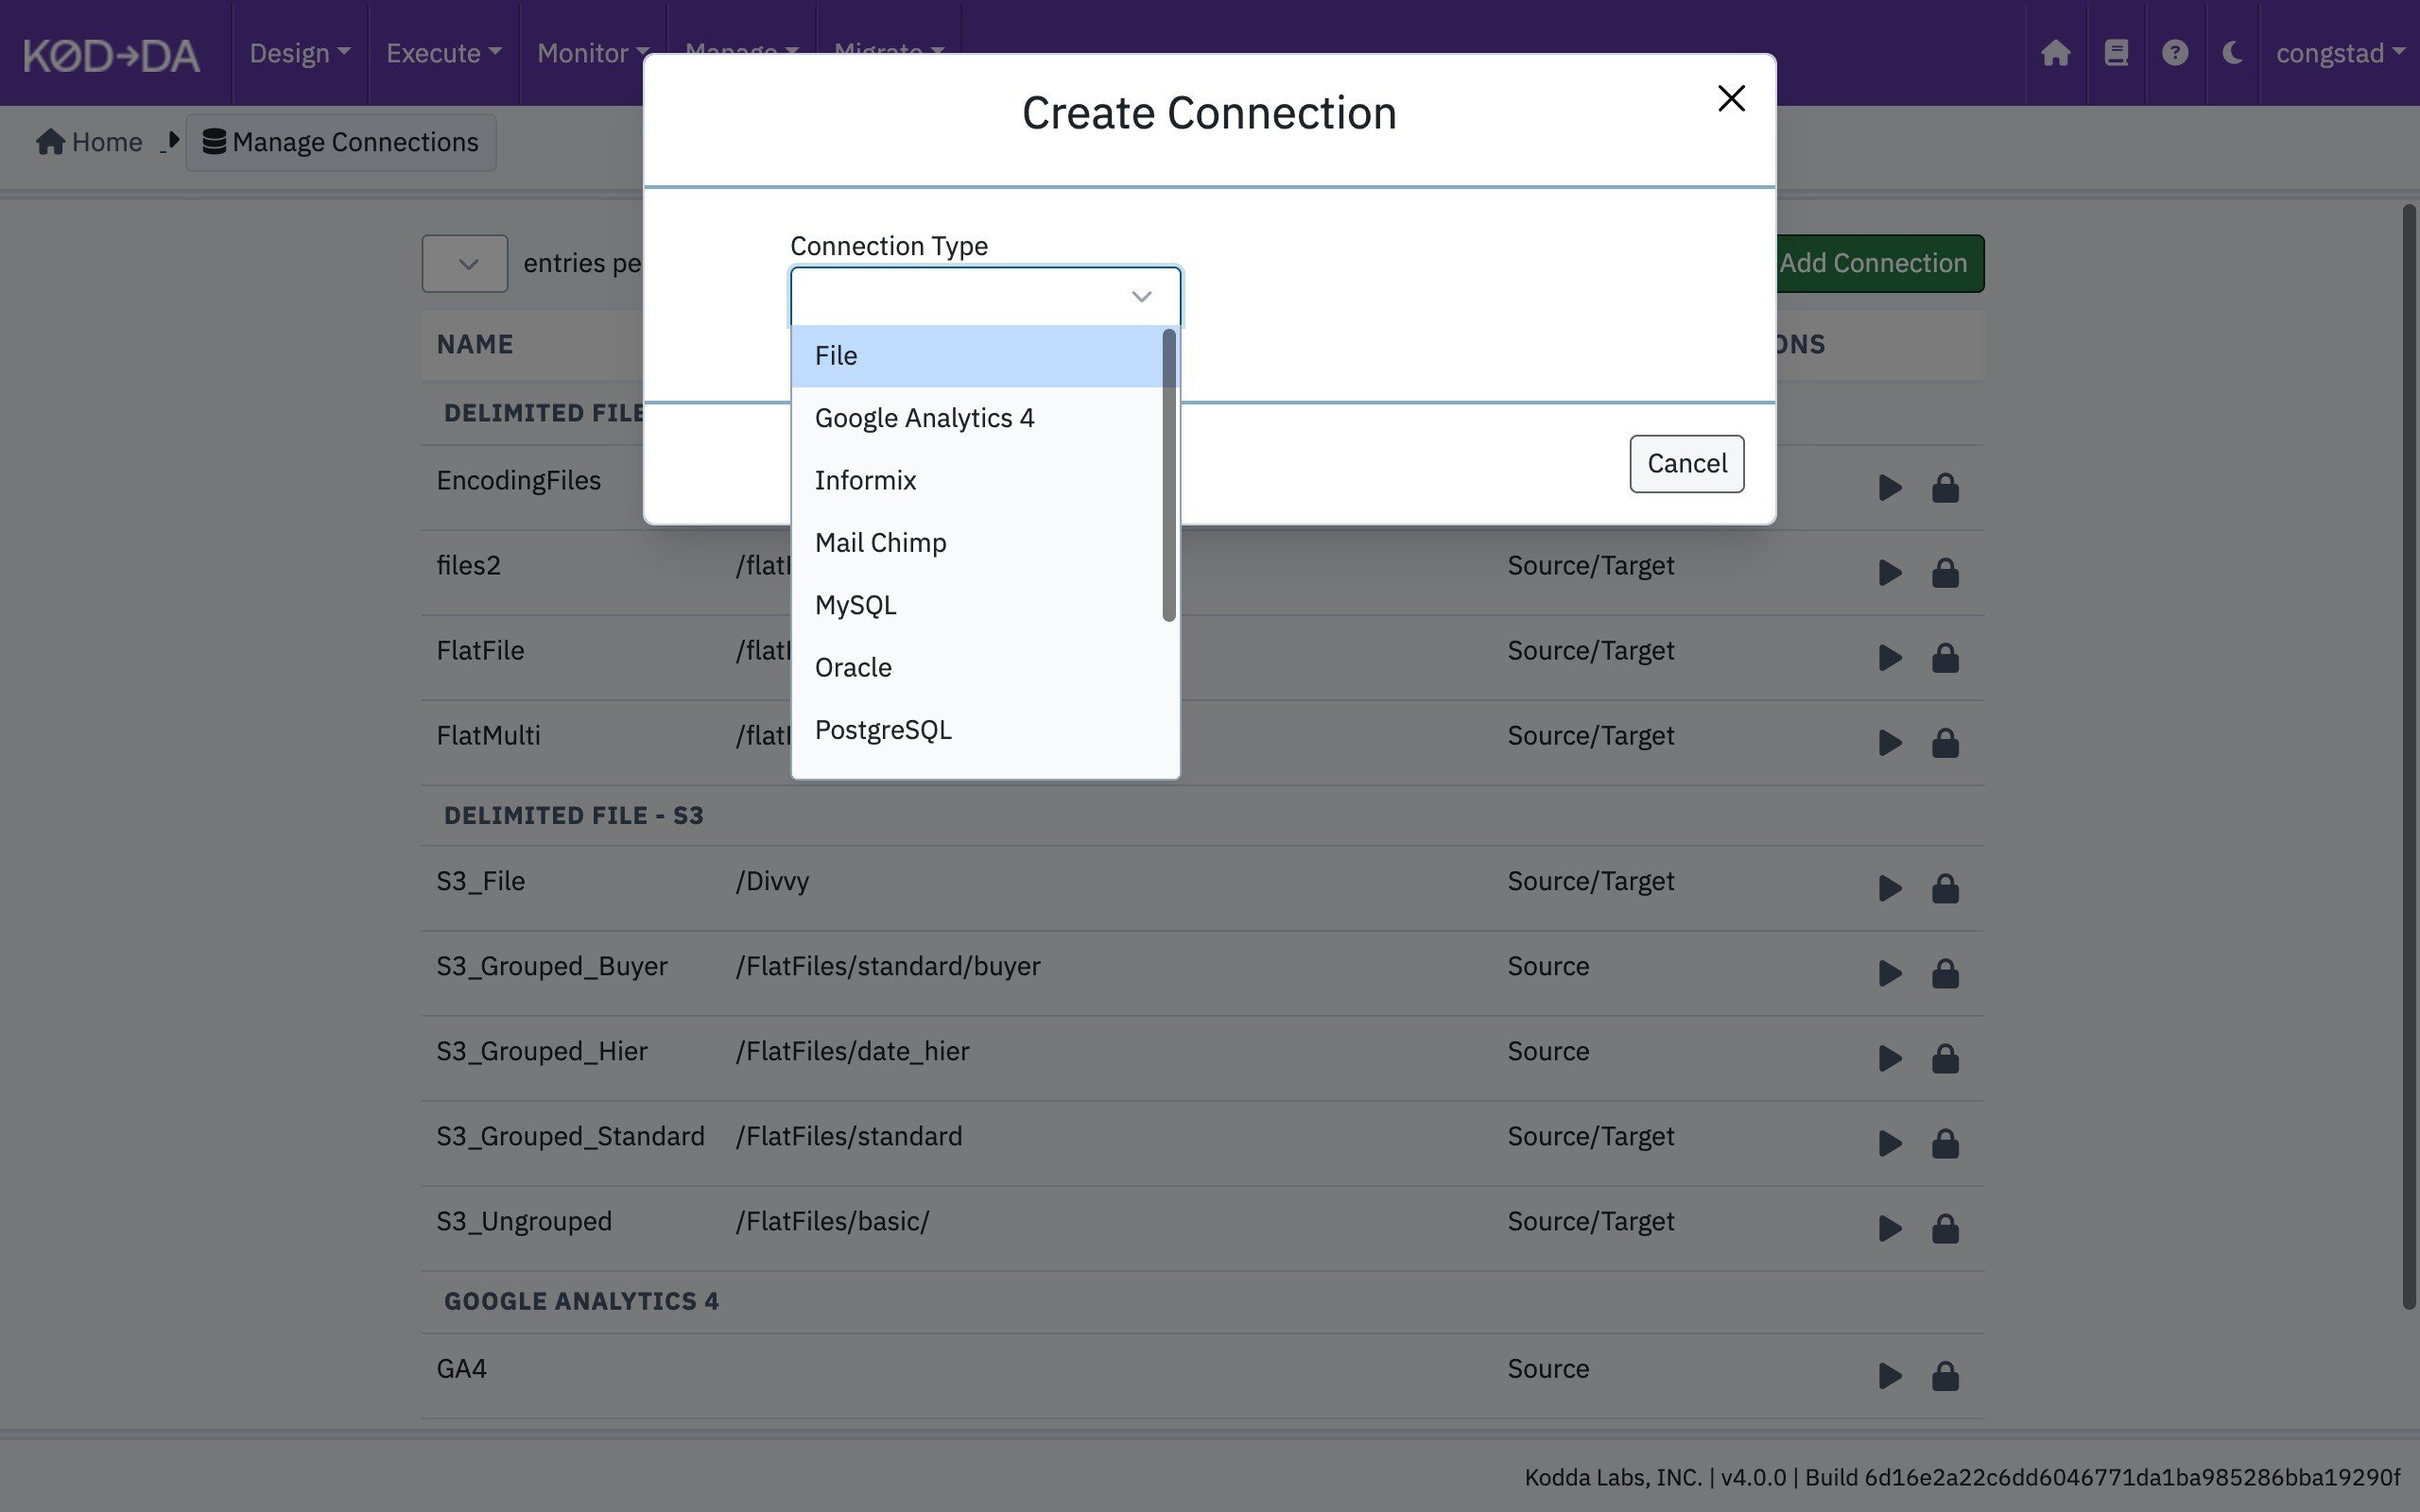
Delimited File
Connection Type: Delimited File (Advanced Settings)
Connection Type: File - Parquet File
Connection Type: Parquet File (Advanced Settings)
Connection Type: File (S3 Settings)
Grouping Files
Use Group Files when many files share the same columns and should be loaded into a single table — for example a new extract delivered every day. Grouping applies to both Delimited and Parquet file connections.How Kodda turns files into tables
With Group Files off, every file in the Directory with the connection’s File Extension is a separate table, named after the file without its extension.department.csv becomes the table department.
With Group Files on, Kodda removes the extension and the part of the name that matches the File Tail Pattern from each file name. Whatever is left is the table name, and all files that end up with the same name are read together as one table.
For example, with the pattern _(\d{4}-\d{2}-\d{2}) and extension csv:
Kodda shows two tables,
client and customer. Reading client reads both client files. Files that don’t match the pattern are not included in any table.
All files in a group must have the same columns in the same order. Kodda works out the table’s columns from the first file it finds.
Turning parts of the file name into columns
Any part of the pattern inside parentheses( ) is captured and added to every row read from that file as an extra column. Name these columns in File Tail Column Names, one name per pair of parentheses, in the same order, separated by commas.
In the example above, setting File Tail Column Names to file_date adds a file_date column containing 2024-01-01 for every row from the first file and 2024-01-02 for every row from the second. Extra columns are always text and are added after the file’s own columns.
Loading only new files
If a file tail column is used as a mapping’s Incremental Column, Kodda compares each file’s value with the last value loaded and skips older files without opening them. This makes incremental loads from large folders much faster. For delimited files, the comparison is done as text. The values must sort correctly as text. Dates inYYYY-MM-DD or YYYYMMDD form, or zero-padded numbers like 0001, work. Dates like 1-2-2024 or unpadded numbers like 9 and 10 do not.
Writing the pattern
- The pattern is matched against the end of the file name, just before the extension. Don’t include the extension; Kodda adds it.
- Start the pattern with the character that separates the table name from the varying part, usually
_or-, so it isn’t left on the end of the table name. - The pattern is a Python regular expression. Commonly used:
\dmatches one digit,\d{4}exactly four digits,\d+one or more digits,.*any characters. - Backslashes can be entered single (
\d) or doubled (\\d); both work. - After saving the connection, open it in Browse Data to check that the tables listed are the ones you expect.
Files in subfolders (S3 only)
On S3 the pattern can include/ to match folders below the Directory. For example, files stored as
/FlatFiles/date_hier/ and pattern /(\d{4}/\d{2}/\d{2}/\d{2})/(.*) give a table named client. The date folders are captured into one column and the file name into another (for example file_system_date,guid).
When the pattern starts with /, Kodda lists only the top-level folders under the Directory to find tables, instead of listing every file. This is much faster in buckets with many files.
On a local file system, Kodda only reads files directly in the Directory, so patterns that span folders don’t work there.
See Loading Files From S3 for a full walkthrough of both layouts.