Details and Settings
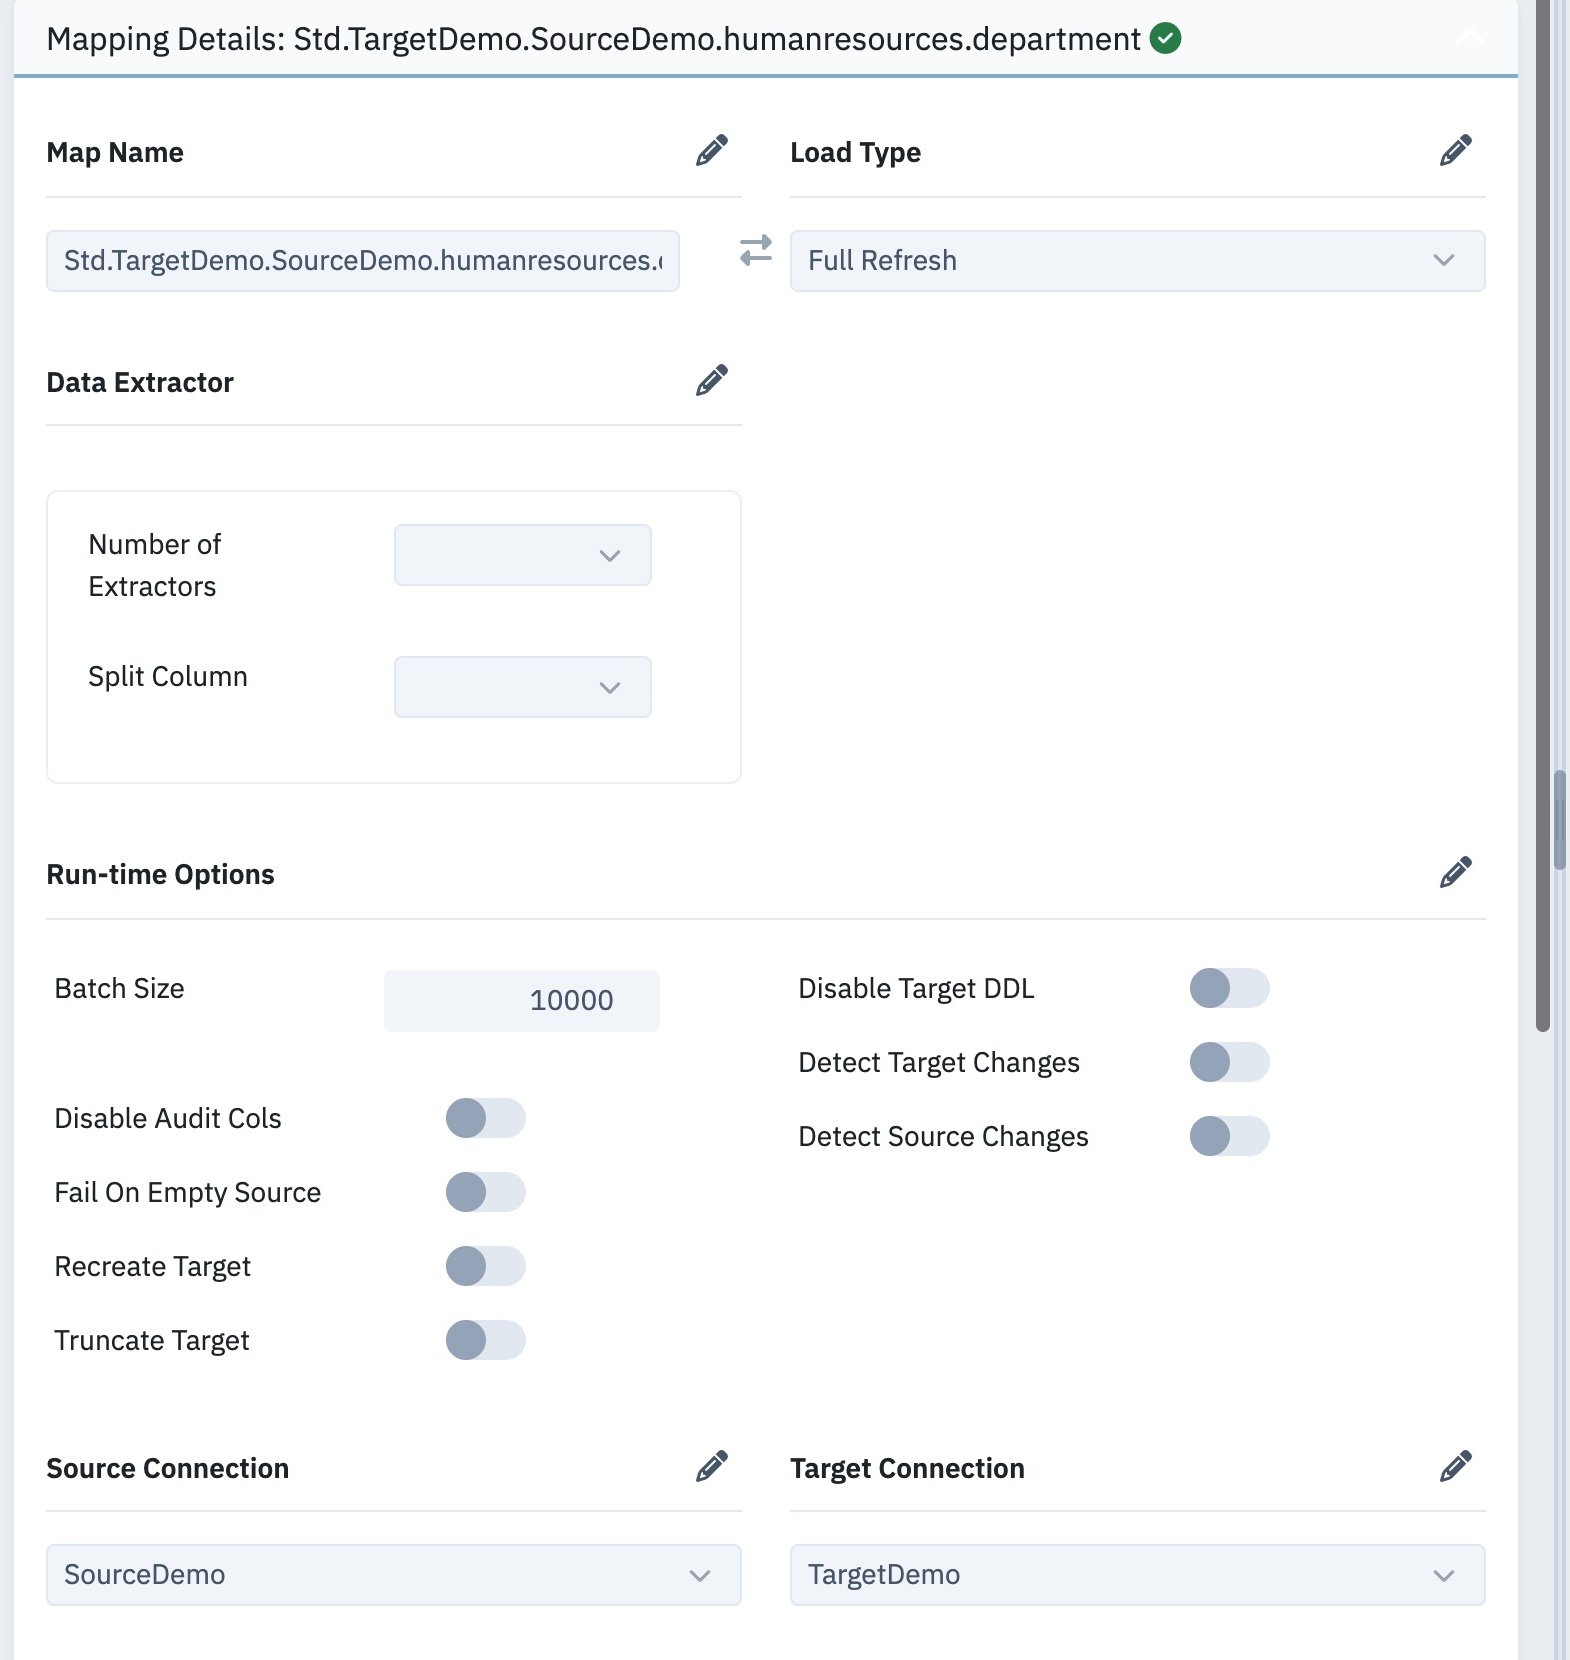
You can access the more granular mapping details by clicking on the Mapping Details header or on the expand/collapse arrow at the right of it.


Map Name
Map Name allows you to change the default name to your own convention. Click the auto-name icon
Load Type
Load Type lets you select one of the available load types, controlling the data ingest process. The load types offered depend on the source and target connection types.
- Append New Records Only identifies the records that do not yet exist in the target table and adds them based on the identified business key. If a record already exists it is ignored.
- Append reads the source data and appends it onto the target table without removing or updating any target data.
- Delete reads the source data and deletes records in the target table that match using the defined Business Key.
- Full Refresh removes all old data from the target table and then does a full load from the source. This is the default load type for new maps generated. Removal is done via SQL Truncate for systems that support Truncate otherwise SQL Delete is used. For files, the entire file is replaced.
- Incremental Change Tracking (SQL Server sources only) leverages change tracking when enabled on SQL Server to detect newly inserted, updated or deleted records. Click the link for an example of how to enable change tracking.
- Incremental Delete uses a column you select to identify new or changed records from the source. A filter on this column is applied on each extract from the source system to limit the number of records read. Records are deleted in the target table by matching on the defined Business Key.
- Incremental Insert uses a column you select to identify new or changed records from the source. A filter on this column is applied on each extract from the source system to limit the number of records read. This is useful for identifying changed records. This requires an incremental column or expression to be defined in order to drive the incremental loads.
- Incremental Insert/Update performs inserts and/or updates of source data changes to the target on each mapping execution. This requires an incremental column or expression to be defined in order to drive the incremental loads. This requires a business key to be defined in the mapping.
- Insert/Update extracts all records from the source and merges them to the target, inserting new records and updating existing ones by matching on the defined Business Key.
- Insert/Update/Delete (Logical) extracts all records from the source system, inserts new records, updates existing records and sets the
si_del_flgcolumn toYwhen a record no longer exists in the source data set. Thesi_del_flgcolumn is added to the target table to identify logically deleted records.
Incremental Load Properties
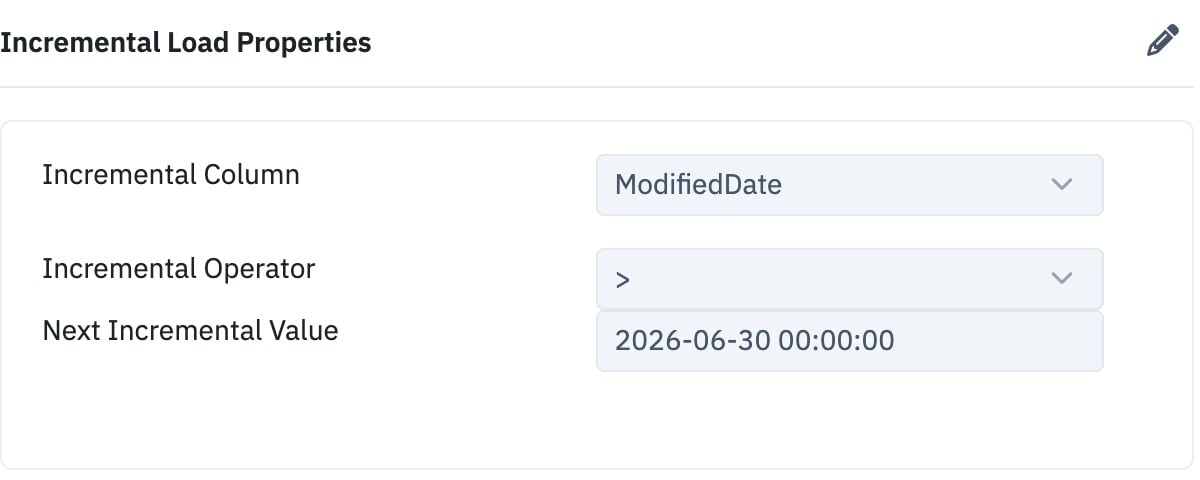
- Incremental Column: A column that can be used to identify newly created or changed records. Ideally this column is a date or integer type.
- Incremental Operator: The comparison operator used when extracting data from the source. This value can be either > (default) or >=.
- Next Incremental Value: The maximum value that was identified the last time the mapping ran. This is the value that will be used on the next run to identify new or changed records.
- Expression: A userdefined SQL expression that can be used as the incremental column. This field is available when the Incremental Column value is set to <CustomExpression>.
Placing the incremental filter in the query
By default Kodda adds the incremental filter to the end of the mapping’s query, and a Custom query is first wrapped asselect ... from ( <your query> ) re_sq where <incremental filter>. If the query has joins, subqueries or aggregates, some database optimizers do not push that outer filter down to the source table, so the whole query is evaluated before any rows are filtered out.
To put the filter where it does the most good, add $incremental(<column>)$ to the query wherever a condition is allowed. This is usually the WHERE clause on the table that holds the incremental column:
- The comparison uses the mapping’s Incremental Operator (
>or>=). The values are passed as quoted strings. - When there is no Next Incremental Value (the first run, or after the incrementals are reset), that half of the filter becomes
1 = 1, so all rows up to the current maximum are read. - Kodda also uses the placeholder in the query that looks up the current maximum value before each run, which speeds up that step too.
- For load types that are not incremental, and in Browse Data and Generate Mapping, the placeholder is replaced with
1=1, so the query still runs as written. - The placeholder is not case-sensitive and can appear more than once, for example in each part of a
UNION. - For SQL Server
rowversioncolumns, use$incremental_ss_binary(<column>)$instead. See Incremental Loads Using Row Version.
Data Extractor
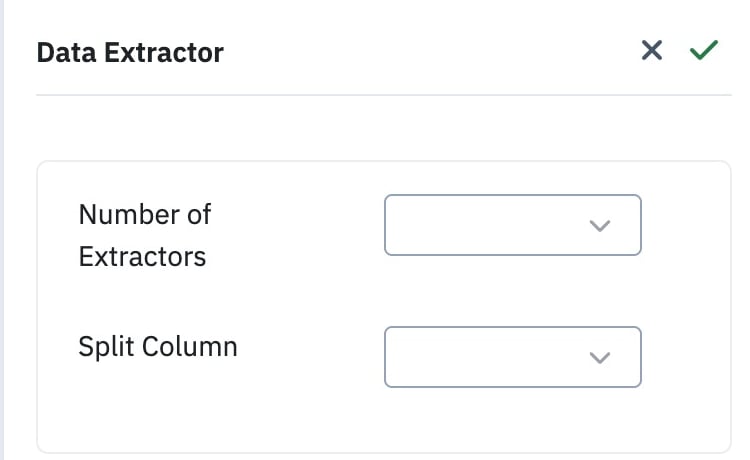
- Number of Extractors: The number of parallel queries (1 to 8) Kodda runs against the source, each handled by its own Data Extractor agent process. Choose a number your source system can handle. With more than one extractor, each one reads the rows where the Split Column modulo the number of extractors equals that extractor’s number (0, 1, 2 and so on). Kodda does not sample the data or calculate row counts, so how evenly the work is shared depends entirely on the split column.
- Split Column: To use multiple Extractors, you must select which INTEGER column in your source data to use to divide the data into a relatively even split between extractors. If you do not have an integer column in your source table you can supply a custom expression that can be used that produces an integer.
- <CustomExpression>: Allows you set the custom expression in order to split the data across multiple extractors. The expression must result in an integer, produce the same result for each row when selecting a single or multiple rows from the table and be valid for use in a “Where Clause” of a query executed in the selected source system. It is highly recommended that the column or expression results in uniformly distributed data across the entire data set being extracted.
Run Time Options
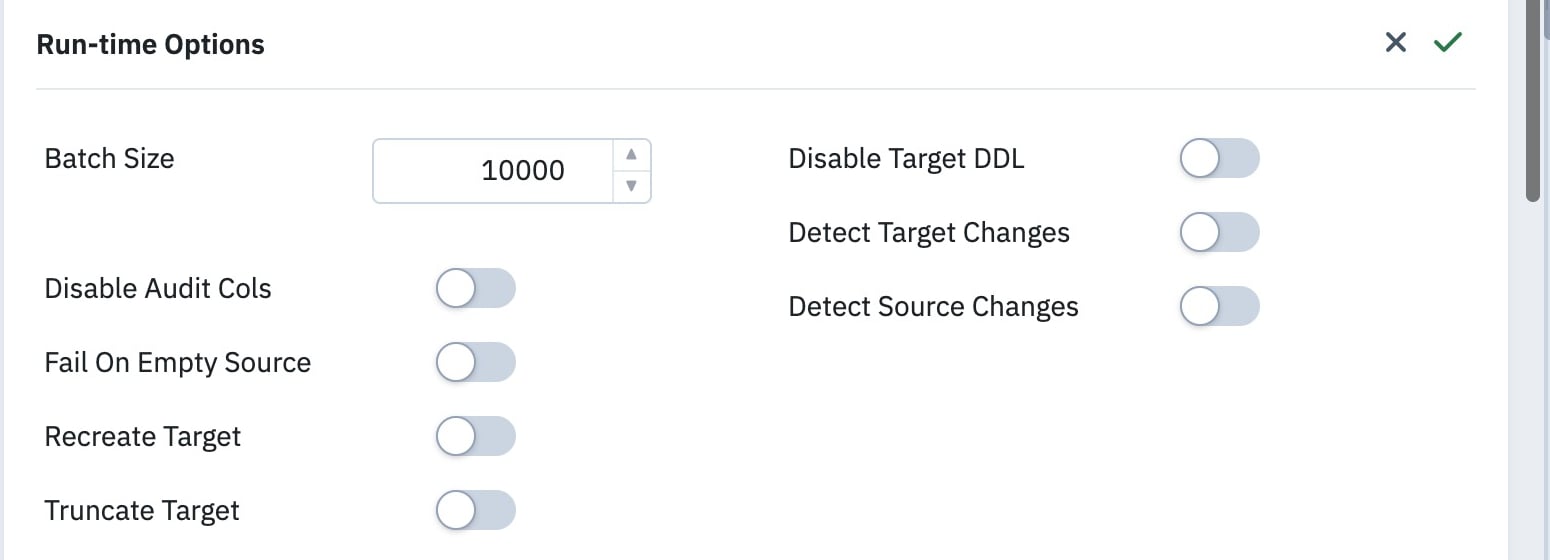
- Batch Size lets you control the number of rows to insert into the target between commit operations.
- Disable Audit Cols disables the use of built-in audit columns in the mappings, This is identical to the Disable Audit Columns option described on the Generate Mapping page.
- Recreate Target drops the target table at the start of the next run, then creates it again from the current mapping definition before loading. The option applies to that one run only: it switches off automatically after the mapping completes successfully.
- Truncate Target removes all rows from the target table at the start of the next run, then loads it using the mapping’s load type. The source is still read using the incremental filter, if the load type is incremental, so only the rows in the current incremental range end up in the table. The option applies to that one run only: it switches off automatically after the mapping completes successfully.
- Disable Target DDL prevents DDL statements from running on the target table when the mapping is run. See Disable Target DDL on the Generate Mapping page.
- Detect Target Changes enables auto-detection of target table changes in the map. This can be used in conjunction with Disable Target DDL to ensure delivery of data when the target structure differs from the source. See Detect Target Changes on the Generate Mapping page.
- Detect Source Changes enables auto-detection of source schema changes in the map. This allows a map to detect when a source schema has changed from what has been defined in the existing mapping, allowing you to run the mapping and automatically add new columns from the source, or ignore columns that no longer exist in the source. See Detect Source Target Changes on the Generate Mapping page.
- File Audit (file sources only) When the source is a delimited or parquet file the file name and record number are appended to the output data set.
- Normalize Date Time (Parquet sources only) For parquet files normalizes timestamps to UTC.
- Skip Bad Files (Parquet sources only) For Parquet sources, when enabled and file grouping is active for the connection, files that do not match the expected schema will be skipped instead of causing the mapping to fail.
- Fail On Empty Source When enabled if 0 records are found in the source table the mapping will end in failure.
Source Connection Name
Source Connection Name lets you point the mapping at a different source connection. The list shows every connection whose role is Source or Both, grouped by connection type.
Target Connection Name
Target Connection Name lets you point the mapping at a different target connection. The list shows every connection whose role is Target or Both, grouped by connection type.